Hi, I'm April! I'm a research engineer at NVIDIA, working on vision language models training and
evaluations, multimodal understanding, and agentic data search & curation flywheels, with a
domain focus in Physical AI.
Outside work, I enjoy photography, traveling, driving with music, and spending time with my
three cats.
Multimodal search and data flywheels for physical AI
Building multimodal embedding-based retrieval and curation system over petabyte-scale video datalake,
supporting data flywheels that powers end to end training loops.
VLM Post-training
Training and evaluating VLMs for AV scene understanding
Post-training VLMs for driving scene understanding, building holistic evaluation and benchmarking
covering caption quality, temporal reasoning, embedding quality, and retrieval behavior, deriving
insights for model selection and identifying failure modes.
Agentic Loop
Agent loops that curate long-tail driving scenarios
Building an agentic search-refinement loop that iteratively search, labels, refines, to curate
datasets, with an evaluation harness that keeps the agents measurable, reproducible, and
self-improving.
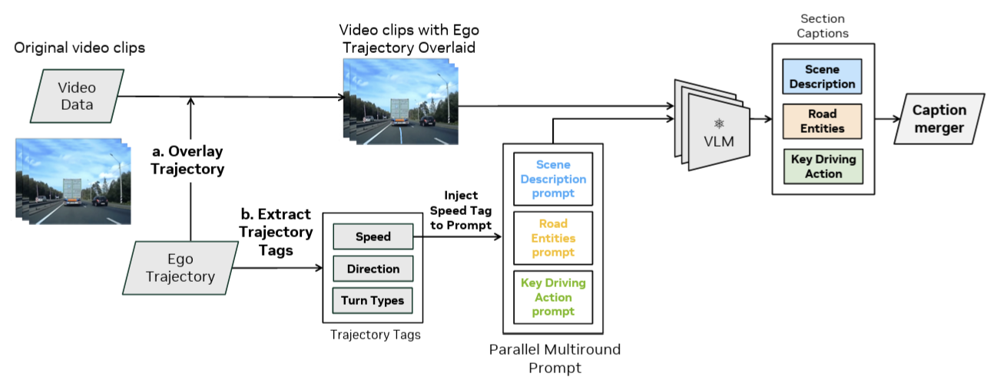
A scalable video captioning framework based on small VLMs that produces diverse
intermediate captions, which are consolidated into a comprehensive unified description for driving
video retrieval.
* Equal contribution
@inproceedings{yang2026scalable,
  title={Scalable Parallel Prompting for Complex AV Video Captioning},
  author={Yang, April and Amoroso, Roberto and Durasov, Nikita and Bisla, Devansh and Kundu, Sandipan and Haussmann, Elmar and Bhargava, Ruchi and Shen, Maying and Chang, Nadine and Alvarez, Jose M.},
  booktitle={Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition Workshops (CVPRW)},
  year={2026}
}
An open-source system for large-scale video data curation that fuses
complementary retrieval signals over tens of millions of clips, closing the loop from model failure
discovery to training and evaluation.
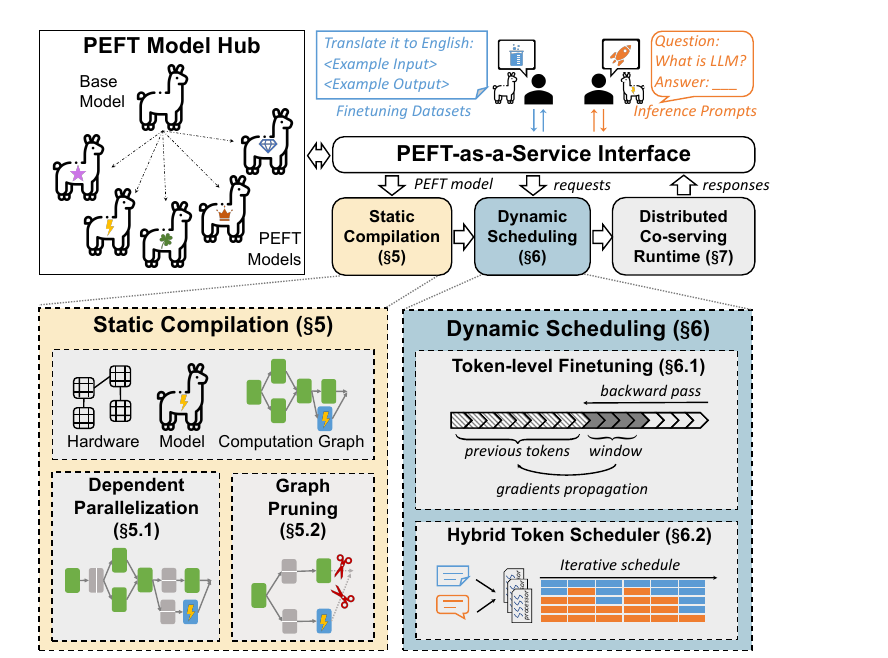
The first system to co-serve LLM inference and parameter-efficient finetuning on
shared GPUs. Token-level fusion lets finetuning soak up idle capacity while inference keeps its
latency SLOs.
@inproceedings{oliaro2026flexllm,
  author = {Gabriele Oliaro and Xupeng Miao and Xinhao Cheng and Vineeth Kada and Mengdi Wu and Ruohan Gao and Yingyi Huang and Remi Delacourt and April Yang and Yingcheng Wang and Colin Unger and Zhihao Jia},
  title = {{FlexLLM}: {Token-Level} {Co-Serving} of {LLM} Inference and Finetuning with {SLO} Guarantees},
  booktitle = {23rd USENIX Symposium on Networked Systems Design and Implementation (NSDI 26)},
  year = {2026},
  isbn = {978-1-939133-54-0},
  address = {Renton, WA},
  pages = {1359--1379},
  url = {https://www.usenix.org/conference/nsdi26/presentation/oliaro},
  publisher = {USENIX Association},
  month = may
}
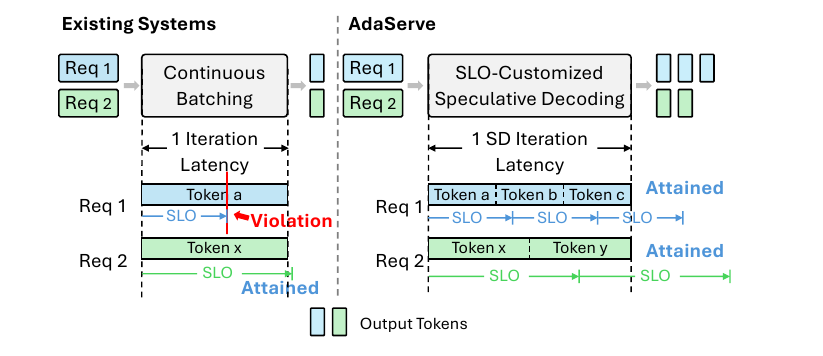
An LLM serving system for requests with different latency targets. SLO-customized
speculative decoding builds a speculation tree per request, meeting heterogeneous SLOs while
maximizing throughput.
@inproceedings{li2026adaserve,
  title={AdaServe: Accelerating Multi-SLO LLM Serving with SLO-Customized Speculative Decoding},
  author={Li, Zikun and Chen, Zhuofu and Delacourt, Remi and Oliaro, Gabriele and Wang, Zeyu and Chen, Qinghan and Lin, Shuhuai and Yang, April and Zhang, Zhihao and Chen, Zhuoming and Lai, Yi-Hsiang and Cheng, Xinhao and Miao, Xupeng and Jia, Zhihao},
  booktitle={Proceedings of the 21st European Conference on Computer Systems (EuroSys)},
  pages={36--54},
  year={2026}
}